Notes from the data floor.
Essays on robotics data, agentic feedback, evaluation, and the decisions that shape a dataset — written by the Agentuor team since May 2025.
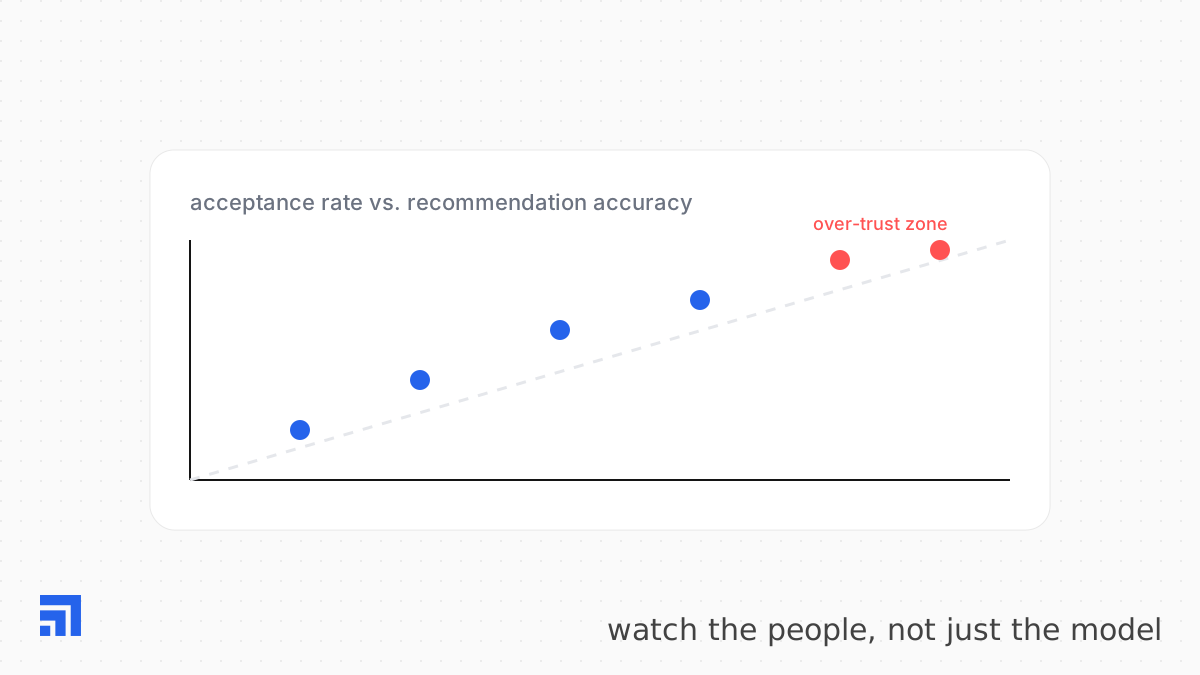
Automation bias in annotation, and how we measure it
The better the agent gets, the more dangerous a rubber-stamping annotator becomes. Here is what we watch.
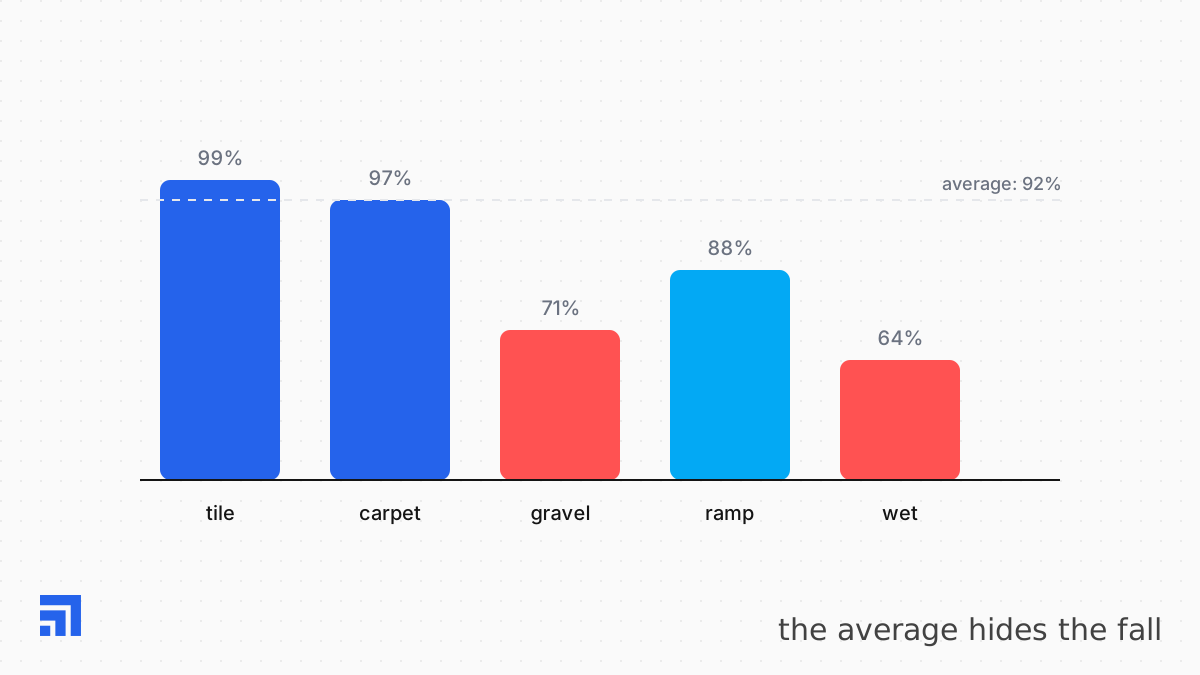
Evaluating humanoid policies by terrain, not by average
A 92% success rate can hide a 64% success rate on wet floors. For a robot walking near people, the second number is the one that matters.
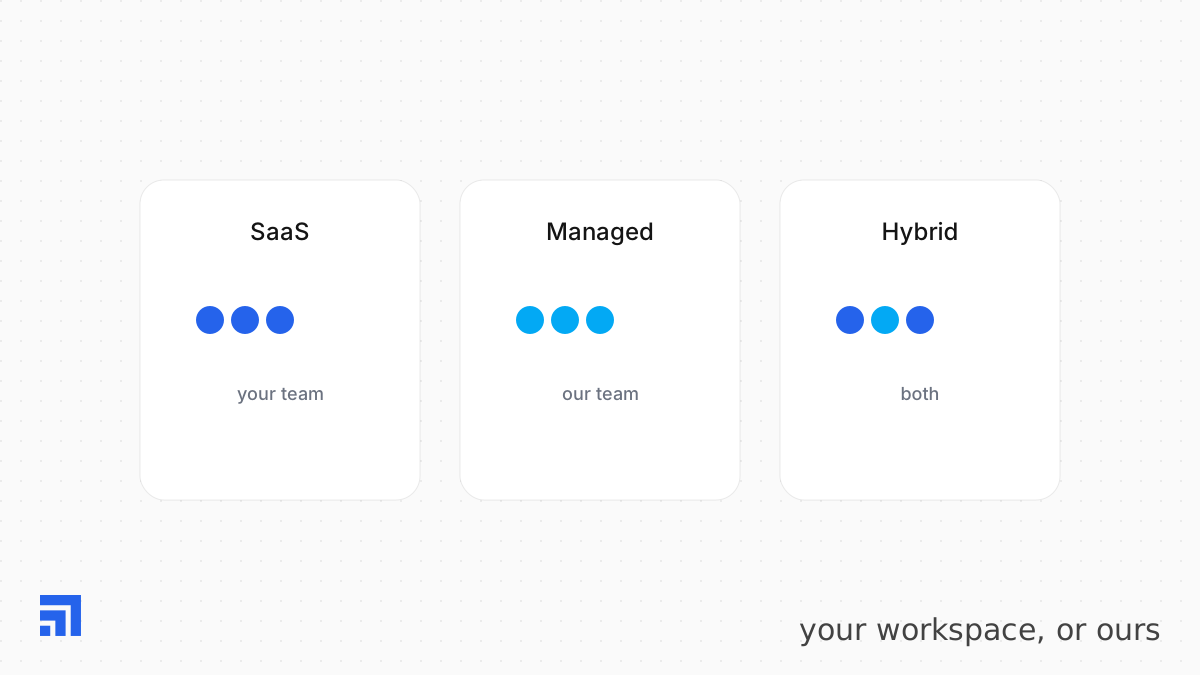
Introducing managed services and hybrid delivery
One year in, teams asked us to run the work as well as the platform. Here is how we do it without losing what makes the platform useful.
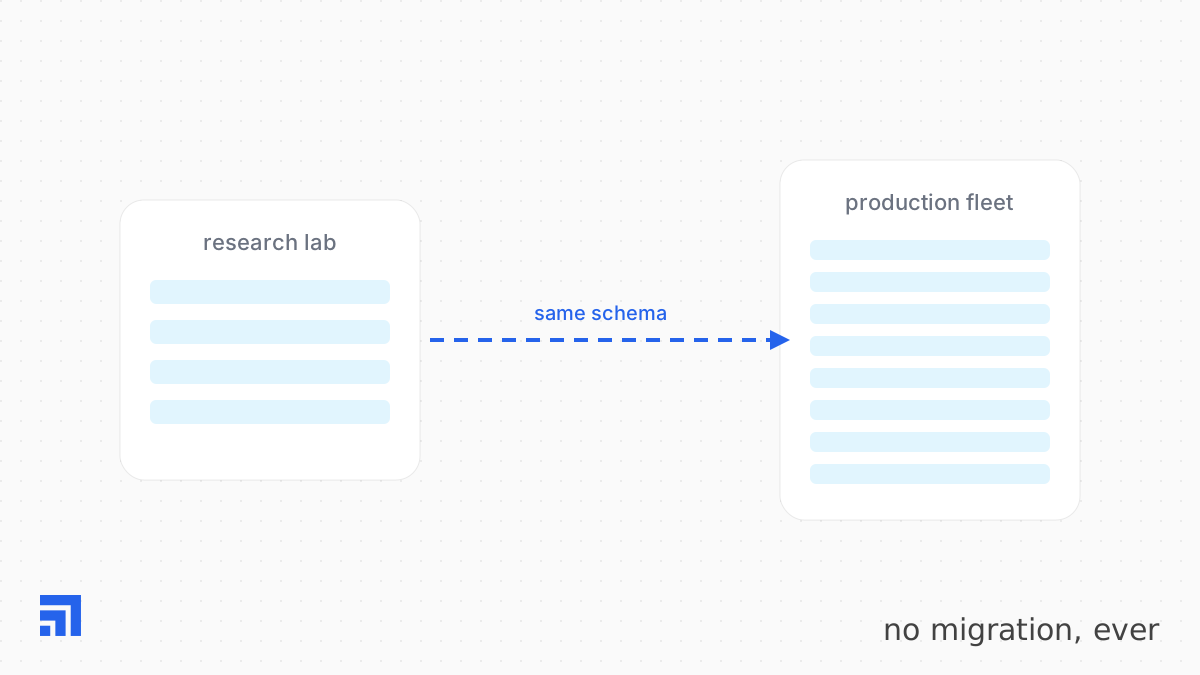
One schema from research lab to production fleet
The dataset a lab starts with should be the dataset the fleet runs on. Here is what that requires.
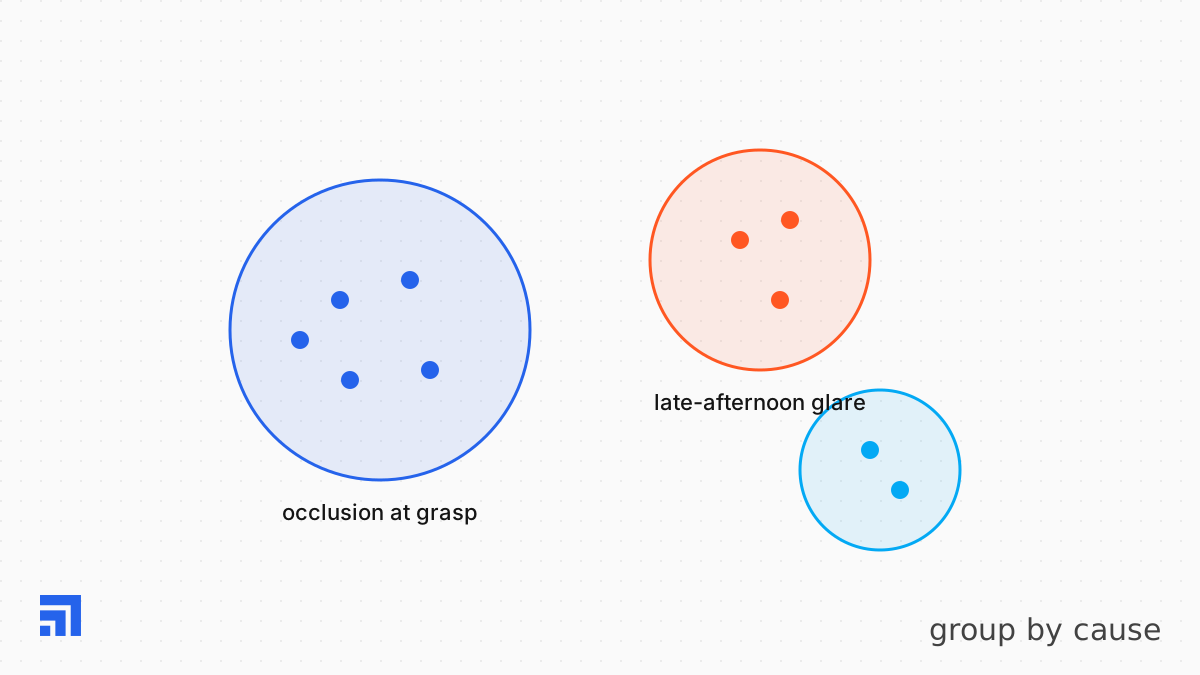
Failure modes, not failures: clustering what breaks
A list of failed episodes is a to-do list. A list of failure modes is a strategy.
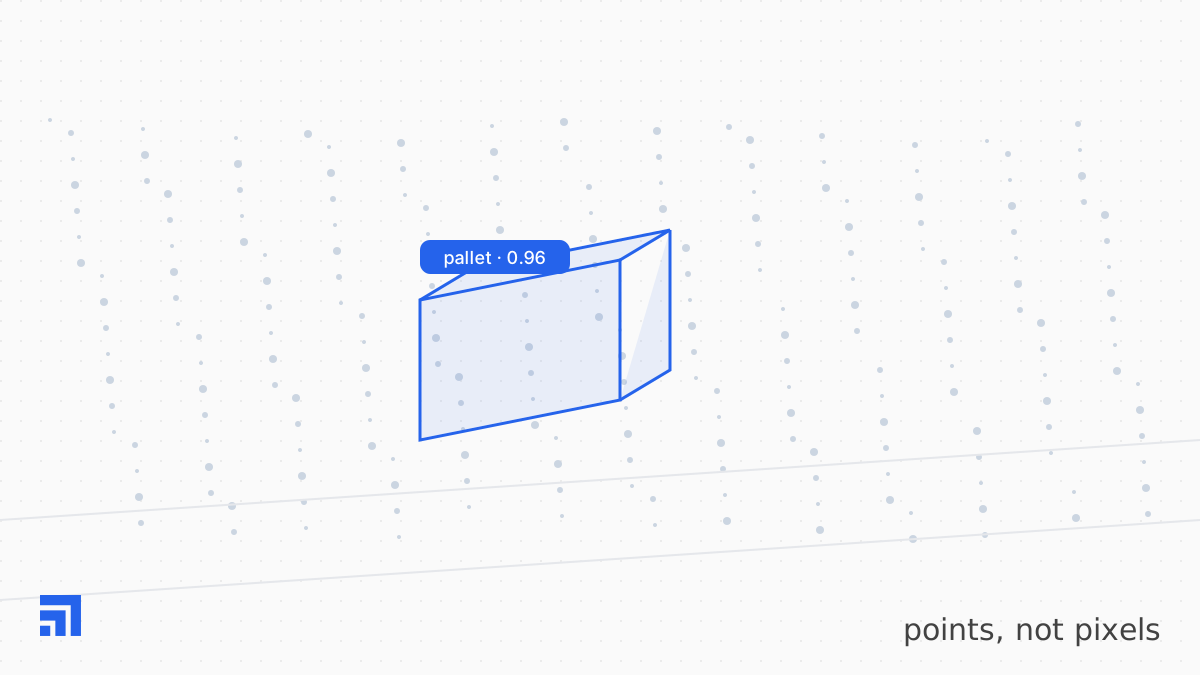
LiDAR annotation for robotics: what image tools get wrong
Point clouds are not pictures. Tools that treat them that way produce boxes that look right and measure wrong.
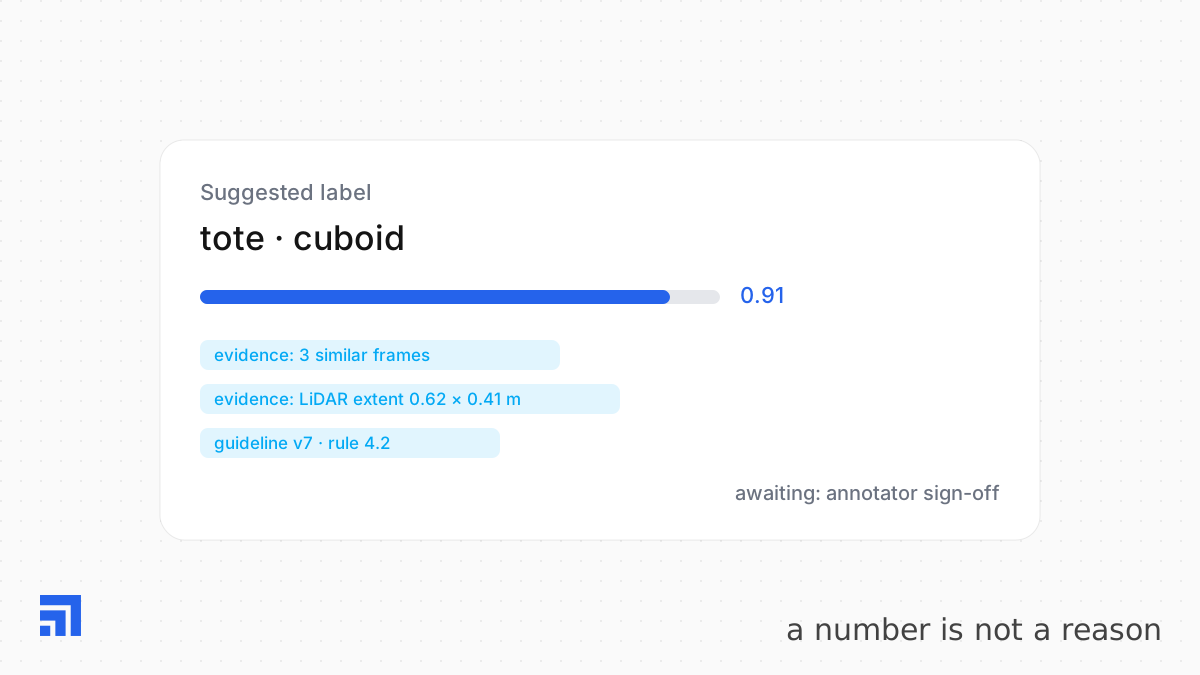
Confidence is not enough: why every recommendation needs provenance
A confidence score invites over-trust. Pairing it with evidence turns a number into something a reviewer can actually judge.
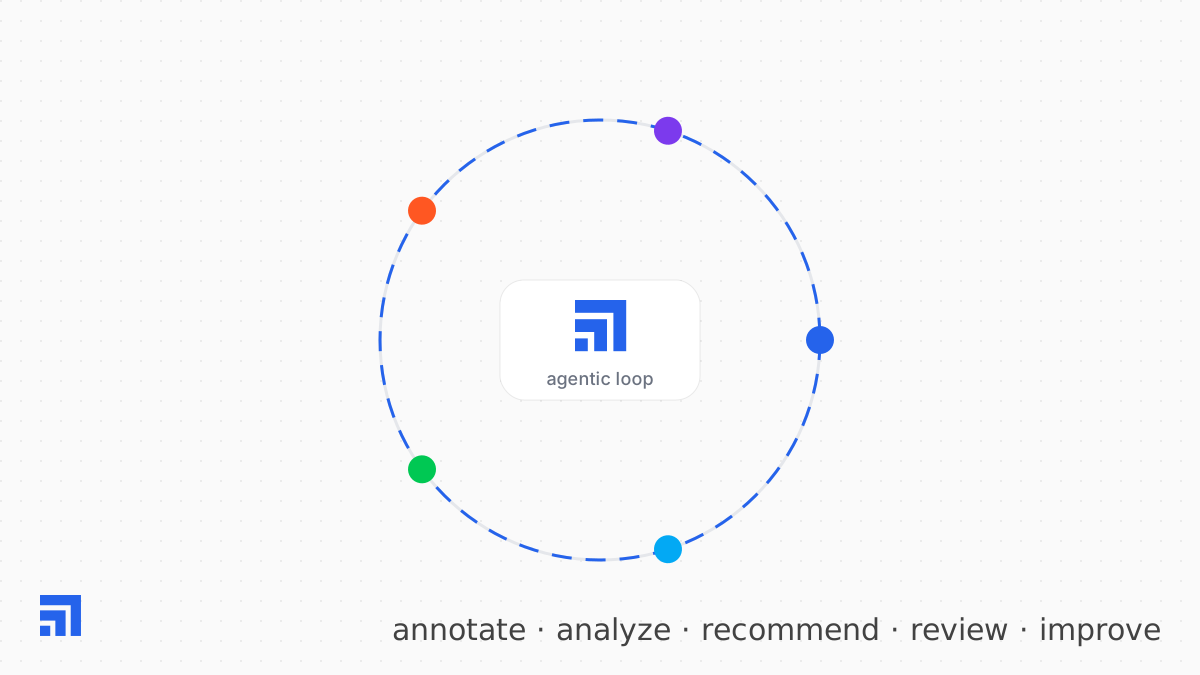
Introducing the agentic feedback loop
Agents that watch annotation as it happens, fold in reviewer decisions, and hand every annotator the context they were missing.
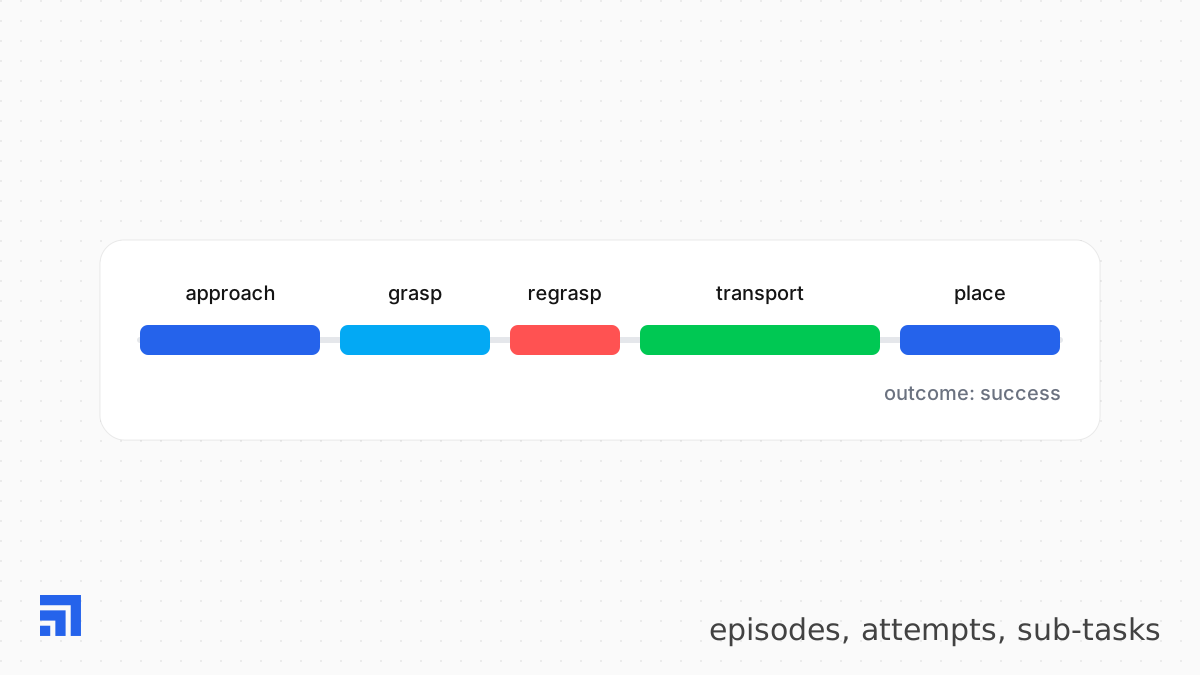
The anatomy of a robot episode
Episodes, attempts, and sub-tasks are not the same thing. Confusing them is the most common structural mistake in robot learning datasets.
Why we started Agentuor
Robot learning teams were spending more time moving data between tools than improving it. We built the platform we wished existed.